Introduction
Chaos engineering has an execution gap. Everyone agrees it is important, but many teams skip it because running a game day on AWS can be expensive and time-consuming. You need a staging environment mirroring production, a fault injection budget, several engineers, and a rollback plan. As a result, teams often discover failures during a production incident in the postmortem instead of before one.
These failures can remain hidden until a dependency has had a bad hour. For example, a queue might safely absorb one outage, while a Lambda function silently drops data during another. From the outside, both situations can look the same.
To address this execution gap, we decided to try an experiment in which an agent would manage the entire game day. Using the LocalStack MCP server, the agent tested a serverless data pipeline. Its task was to define normal behavior, break one dependency at a time, diagnose and fix each problem, and replay the same faults to verify the fixes. No human input was needed until the report was ready.
The agent found and fixed two hidden failure modes. At the start of the pipeline, a slow dependency caused requests to fail with an unclear error. At the end, the pipeline lost metrics but still reported success. The agent then repeated its fault tests to verify both fixes. Here is how the session worked and how agents can help test your cloud application.
The tools: fault injection and traces
Two LocalStack capabilities carry this experiment, both exposed to the agent as MCP tools.
The Chaos API injects faults directly into LocalStack. Each fault rule specifies which service to target, the error to return, and how often it should occur. You can also limit the rule to a specific operation or region. While the rule is active, matching API calls fail as if the real dependency were unavailable. This triggers normal application behavior such as SDK retries, timeouts, and poller backoffs. For example, probability: 0.4 makes 40% of matching calls fail, creating a brownout rather than an outage.
App Inspector records activity inside LocalStack as traces. A trace follows one flow through the system, while each span represents an AWS API call. Span events show what happened during that call. This helps you find not only that data was lost, but also where it was lost. You can follow a record from the API Gateway request through each step and see the exact call that failed, along with its error.
The MCP server gives the agent access to both capabilities. It also provides tools to start LocalStack, deploy CDK projects, and run AWS CLI commands. Instead of writing custom scripts, you can simply tell the agent what to test.
Prerequisites
- Docker and a valid
LOCALSTACK_AUTH_TOKEN - Node.js for the MCP server
- Claude Code, or any other MCP client
cdklocaland Go for the sample app
Step 1: Set up the MCP server
The MCP server comes with a wizard that writes the client configuration for you:
npx -y @localstack/localstack-mcp-server initThe command checks that Docker is available and reads LOCALSTACK_AUTH_TOKEN from your environment. If the token is missing, it asks you to enter it. It then finds installed MCP clients such as Claude Code, Cursor, VS Code, and Codex, and configures the ones you select. The LocalStack tools will be available the next time you start your agent.
Step 2: A pipeline that had never been chaos tested
We used the serverless-data-processing-pipeline sample application, a CDK application written in Go. Each record sent to API Gateway passes through four stages:
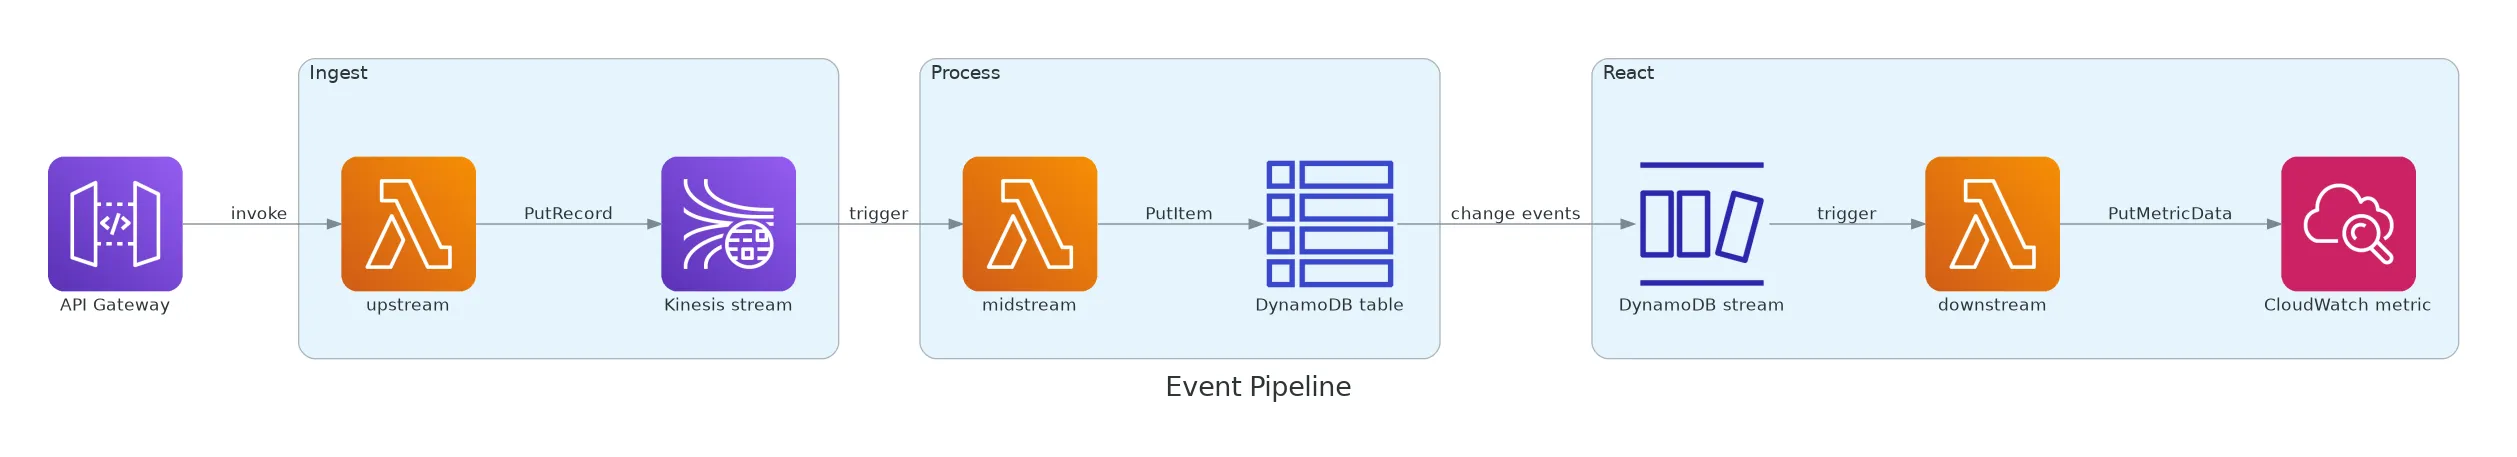
The upstream Lambda sends each record to Kinesis. The midstream Lambda reads it from Kinesis and writes it to DynamoDB. Finally, the downstream Lambda reads the DynamoDB stream and publishes a latency metric to CloudWatch.
Under normal conditions, the pipeline works as expected: sending 60 records produces 60 rows in DynamoDB. However, it was built to measure processing time, not to handle dependency outages. Each handler attempts its write once.
What happens next depends on where the failure occurred and on the default AWS behavior for that service. This makes the app a useful example of many production pipelines that have never been chaos tested, which is the point of the experiment.
Step 3: The assignment
We opened claude in the repository and gave it a goal instead of detailed instructions. Here are the key parts of the assignment:
Run a chaos game day against the serverless data pipeline in this repository.The pipeline has never been tested for dependency failures. Find any problems,fix them, and verify your fixes.
1. Start LocalStack, enable App Inspector, and deploy the app as-is.2. Define the expected steady state before injecting faults. Measure it once   under normal conditions.3. Inject realistic faults at each stage of the pipeline. Send traffic while   each fault is active because every stage may respond differently.4. Diagnose each failure before changing the code. Use App Inspector traces,   spans, and span events as your main evidence.5. Fix each problem. The pipeline must not lose accepted data or hide failures.6. Repeat the same tests with traffic and confirm that the fixes preserve the   steady state.
The agent decided which faults to inject, how to define the steady state, and how to fix each problem.
Step 4: The agent prepares the test
Two parts of the setup stood out.
First, the agent used the MCP server to start LocalStack, enable tracing, and deploy the stack:
● localstack-management(action: "status")● localstack-management(action: "start", envVars: {"DEBUG": "1", …})● localstack-app-inspector(action: "set-status", status: "enabled")● localstack-deployer(action: "deploy", projectType: "cdk") ⎿ ✅ ServerlessDataProcessingPipelineStack Outputs: ApiGatewayMethodEndpoint, DynamoDBTableName, KinesisStreamName Total time: 34.4sThe deployer tool handles the CDK commands. The agent did not need to run cdklocal directly, and it later used the same tool to deploy its fix.
Second, the agent defined normal behavior before injecting any faults. It wrote down two rules:
H1 (durability) - Every record that receives a 200 response appears exactly once in DynamoDB within 90 s. A record the pipeline refuses loudly is not owed anything.H2 (observability) - Any record the pipeline cannot deliver must surface as a failed invocation, a non-2xx response, or a DLQ entry. No hop may log the problem and continue.The agent created five fault tests. Three simulated complete outages of Kinesis, DynamoDB, and CloudWatch. Another made DynamoDB throttle half of all requests, while the last added 800 ms of network latency.
Next, it built a small probe that sends several concurrent records, each with a unique ID. The tool checks whether every accepted record reaches DynamoDB and reports lost records, dead-letter queue size, and processing times. The baseline passed: 60 records sent, 60 accepted, 60 delivered, and none lost. The median processing time was 4.48 seconds.
Step 5: Breaking it
Every test followed the same process. The agent injected a fault, confirmed that it was active, sent traffic, and then removed the fault. Finally, it checked that every accepted record reached its destination.
Experiment 1: Kinesis down
● localstack-chaos-injector(action: "inject-faults", rules: [{service: "kinesis", operation: "PutRecord", region: "us-east-1", probability: 1, error: {code: "ServiceUnavailable", statusCode: 503}}])● localstack-chaos-injector(action: "get-faults") ⎿ [{"service": "kinesis", "operation": "PutRecord", "probability": 1.0, …}]None of the 30 requests were accepted. Every caller received an unclear 502 Internal server error. This was unexpected because the upstream Lambda was designed to return a more useful 500 error. The agent checked the traces to find out why that error never appeared:
● localstack-app-inspector(action: "list-spans", trace_id: "*", operation_name: "PutRecord", limit: 8) ⎿ 6443d6ece1fac631 | kinesis | PutRecord | status 2 | 16:05:44.086 613c365e037f1e59 | kinesis | PutRecord | status 2 | 16:05:44.168 … Pagination: Total: 150The traces showed 150 PutRecord calls, including 60 successful calls from the baseline test. During the fault, the remaining 90 calls failed across 30 requests. The AWS SDK tried each request three times before Lambda stopped the invocation. Each failed trace included the record and the injected error:
"localstack.aws.service.request": {"StreamName": "KinesisStream", "Data": "{\"id\":\"exp1-kinesis-down-…-26\", …}"},"localstack.aws.service.exception": {"code": "ServiceUnavailable", "status_code": 503}The Lambda used CDK’s default 3-second timeout, but the SDK retries took longer. Lambda stopped each invocation before the retries finished, as shown by Duration: 3000.00 ms … Status: timeout in the logs. The handler never had time to return its own error response.
Experiment 2: DynamoDB down
The agent injected the same type of fault at the next stage of the pipeline. The result was completely different:
● localstack-chaos-injector(action: "inject-faults", rules: [{service: "dynamodb", operation: "PutItem", region: "us-east-1", probability: 1, error: {code: "ServiceUnavailable", statusCode: 503}}])The agent sent 30 records and kept DynamoDB unavailable for 45 seconds. During that time, the midstream Lambda repeatedly failed. The agent then removed the fault and checked how many accepted records were delivered:
{"label": "exp2-ddb-down", "sent": 30, "accepted": 30, "refused": 0, "delivered": 30, "lost": 0, "steady_state_holds": true, "latency_p50": 63.32, "latency_p95": 64.67}All 30 records arrived about a minute late. The Kinesis event source mapping retried the batch until DynamoDB recovered. Because each write uses the record’s id as its key, retries overwrite the existing item instead of creating duplicates.
The API at the start of the pipeline did not retry, while this middle stage retried indefinitely. Both behaviors came from default settings rather than deliberate choices.
Although no data was lost, the test exposed a risk: this resilience was accidental. The mapping had no bisectBatchOnError, reportBatchItemFailures, maxRecordAge, or failure destination. Unlimited retries saved these 30 records, but they could also let one permanently invalid record block an entire shard. The same behavior can either protect or stall the pipeline.
A follow-up test produced ProvisionedThroughputExceededException for 50% of PutItem calls. All 40 records were eventually delivered, but with higher latency and the same unlimited retry behavior.
Experiment 3: 800 ms of latency
● localstack-chaos-injector(action: "inject-latency", latency_ms: 800)The network was slower, but no service failed. Even so, none of the 20 requests were accepted, and every caller received a 502. Adding 800 ms to each AWS call caused the Lambda to exceed its 3-second timeout. A slow dependency alone was enough to make the API unavailable.
Experiment 4: CloudWatch down
The final stage publishes one latency metric for each record. When PutMetricData was unavailable, the agent noticed that Lambda reported no failures. It checked the downstream Lambda’s results for the entire test:
items seen by downstream: 120'Error recording latency' lines: 120lambda invocations reported as error: 0The cause was the Go handler signature: func(ctx, events.DynamoDBEvent). Because it did not return an error, the handler could not report a failure. It logged metric errors and continued, so each invocation appeared successful. The stream then moved past records whose metrics were never published.
A malformed record caused another problem. A bare return stopped the handler and silently skipped the rest of the batch. DynamoDB still stored every row, but the pipeline lost both the metrics and any signal that they were missing.
Step 6: The fix
The agent updated all three Lambda handlers and the CDK stack. It then deployed the changes with the same deployer tool used during setup. The fix had four parts.
Upstream: Keep retries within the timeout
The agent limited the number of SDK retries. It also gave each Kinesis call a deadline based on the remaining Lambda execution time, leaving enough time to return a response:
const (    putRecordMaxRetries  = 4    deadlineSafetyMargin = 1500 * time.Millisecond)
sess := session.Must(session.NewSession(&aws.Config{    Endpoint:   endpointUrl,    MaxRetries: aws.Int(putRecordMaxRetries),}))
func callDeadline(ctx context.Context) (context.Context, context.CancelFunc) {    if deadline, ok := ctx.Deadline(); ok {        if remaining := time.Until(deadline) - deadlineSafetyMargin; remaining > 0 {            return context.WithTimeout(ctx, remaining)        }    }    return context.WithCancel(ctx)}
The handler now has enough time to return a clear response. If Kinesis is unavailable, the caller receives a 503 error instead of a timeout:
HTTP/2 503retry-after: 1
{"message":"rejected: could not durably enqueue record v2-verify-1:  ServiceUnavailable: Operation failed due to a simulated fault"}
Midstream: Retry only failed records
The handler now returns a partial batch response that identifies each failed record. One bad record no longer causes the entire batch to be retried:
func HandleRequest(ctx context.Context, kinesisEvent events.KinesisEvent) (events.KinesisEventResponse, error) {    var response events.KinesisEventResponse
    fail := func(seq string, format string, args ...interface{}) {        fmt.Printf("ERROR "+format+"\n", args...)        response.BatchItemFailures = append(response.BatchItemFailures,            events.KinesisBatchItemFailure{ItemIdentifier: seq})    }    // per-record processing; undecodable records call fail() instead of aborting
Downstream: Return failures
The original handler could not return an error. The agent changed its signature from func(ctx, events.DynamoDBEvent) to:
func handleRequest(ctx context.Context, e events.DynamoDBEvent) (events.DynamoDBEventResponse, error)Metric publishing failures are now logged at ERROR and returned as failed batch items. This allows the event source to retry them.
Stack: Limit retries and capture failures
Returning failures only helps if the event source mappings respond to them. The agent configured bounded retries, partial batch handling, and a dead-letter queue:
lambdas["midstream"].AddEventSource(awslambdaeventsources.NewKinesisEventSource(stream, &awslambdaeventsources.KinesisEventSourceProps{ // Retry until the record ages out: this is what lets an accepted // record survive a multi-minute DynamoDB outage. MaxRecordAge: awscdk.Duration_Hours(jsii.Number(4)), // Narrow a failing batch down to the offending record. BisectBatchOnError: jsii.Bool(true), ReportBatchItemFailures: jsii.Bool(true), OnFailure: awslambdaeventsources.NewSqsDlq(dlq), }))The DynamoDB stream received similar settings, but with tighter limits: five retry attempts and a maximum record age of one hour. This stage handles metrics rather than the original record, so a long CloudWatch outage should send failures to the dead-letter queue instead of blocking the stream.
The agent also replaced the default 3-second timeout with timeouts of 15 and 30 seconds for the relevant stages. These values give each retry policy enough time to finish.
The pipeline still allows accepted records to survive a multi-minute DynamoDB outage, as seen in experiment 2. The difference is that retries are now limited, failed batches can be split, and records that still fail are sent to a queue for investigation:
● localstack-deployer(action: "deploy", projectType: "cdk")Step 7: Replaying the faults
The agent repeated the baseline test and all five fault tests. As before, it sent traffic while each fault was active.
| Fault | Before | After |
|---|---|---|
| None | 60/60 delivered, median 4.48s | 60/60 delivered, median 3.45s |
| Kinesis unavailable | 0/30, unclear 502 |
0/30, clear 503 with Retry-After and the record ID |
| DynamoDB unavailable | 30/30 in 63s through unlimited retries | 30/30 in 61s through limited, observable retries |
| Brownout, 50% throttling | 40/40 | 40/40 |
| 800 ms network latency | 0/20 accepted | 20/20 accepted |
| CloudWatch unavailable | 120 failures, none reported | All failures reported |
The pipeline still cannot accept records during a complete Kinesis outage because it has nowhere else to store them. However, callers now receive a clear error telling them to retry. This gives clients enough information to recover instead of treating the response as an unknown failure.
The final stage showed the clearest improvement. Failures that previously disappeared now reached the dead-letter queue with a reason attached. The agent confirmed this by reading the queue through the AWS client tool:
● localstack-aws-client(command: "sqs receive-message --queue-url …/PipelineDlq…") ⎿ {"requestContext": {"functionArn": "…LambdaDOWNSTREAM…", "condition": "RetryAttemptsExhausted", "approximateInvokeCount": 6}, "DDBStreamBatchInfo": {"batchSize": 37, "shardId": "shardId-…", …}}The agent then removed all injected faults and confirmed that none remained:
● localstack-chaos-injector(action: "clear-all-faults")● localstack-chaos-injector(action: "get-faults") ⎿ No chaos faults are currently active● localstack-chaos-injector(action: "get-latency") ⎿ 0msWe then manually repeated the key checks against the running LocalStack environment. During a complete Kinesis outage, the API returned 503 with Retry-After and identified the affected record. With 800 ms of added latency, all 8 new records were accepted; the original pipeline had accepted none. The dead-letter queue also contained 27 RetryAttemptsExhausted entries from the downstream function, making those failures visible.
What this looked like from the outside
The session took 26 minutes and used $8.23 in tokens. It required no AWS spending or staging environment. The agent made 37 MCP tool calls, including 22 calls to the chaos injector. Injecting each fault was quick; most of the work involved observing the pipeline while the fault was active.
This workflow is not limited to Claude Code. The MCP server also works with Cursor, Copilot, Codex, and other compatible clients. The same init command configures each one.
Summary
We asked an agent to break a serverless pipeline and run a complete game day. It first defined what correct behavior meant. It then injected five faults while sending traffic and used traces to investigate each failure.
Each stage revealed a different problem. The API failed because its timeout was shorter than the SDK retry process. The middle stage survived through unlimited retries, which could also let one invalid record block a shard. The final stage failed to publish every metric but still reported success because its handler could not return an error.
The agent fixed these problems with controlled retry limits, partial batch responses, a handler that returns errors, bounded record ages, batch splitting, and a dead-letter queue. After the fixes, the latency test improved from 0 of 20 accepted records to 20 of 20. The final stage no longer hides failures: they now surface as error results and dead-letter queue entries.
These behaviors only appeared when faults were injected and traced. A test that once required a staging environment and a coordinated team took 26 minutes of unattended work.
Try it with the LocalStack MCP server, the Chaos API, and App Inspector.